DEEP DIVE · #01 / THE LOCAL LAB
Build a home agent lab
Windows, Python and Google ADK. A real local build, mistakes included.
Built & written by Luca Viscomi
Production AI agent engineering, Model Context Protocol tooling, multi-agent architecture and context optimisation — built, tested and documented in public.
MSc Artificial Intelligence · Distinction

Explainer Series
Plain-English guides for managers, executives, and leaders moving from AI hype to practical business execution.
The plain-English executive guide to what AI actually does in business.
Watch the 1:25 video intro on the left for the executive breakdown of tools that talk vs systems that work, or read the full article.
Developer Tooling · Open Source
The AI Systems Engineering Harness for Claude Desktop & Cursor. Real token accounting, tool audits, and Layer 1–7 blueprints.
4 Production Tools In Your Chat
Audit tool schemas, count real BPE tokens, harden system prompts, and retrieve LangGraph blueprints directly in Claude Desktop.
⚡ Setup in 30 SecondsStop blaming the model when agents break in staging. Give Claude deterministic tools.
Connects directly into Claude Desktop or Cursor over standard I/O (stdio) or HTTP/SSE on Render.
Telemetry · Active Optimization
Live session telemetry, deterministic transcript surgery, and repository token budgeting to defeat runaway context bloat.
Stop burning tokens on zombie terminal logs, test failures, and unchecked context saturation.
Watch the 1:24 video intro for the complete breakdown of transcript surgery, or launch the interactive browser simulator.
Conversational Telephony · 2026 Benchmark
Sub-600ms latency pipelines, interactive ROI telemetry, and in-depth engineering comparison across the 8 leading platforms.
Sub-600ms latency pipelines, turn-taking & barge-in, HIPAA guardrails, and real-time telephony pricing.
Comprehensive engineering comparison of Bland AI, ElevenLabs, Retell, Vapi, Synthflow, Air AI, Phonely, and PlayAI across enterprise latency, SIP trunking, and compliance.
AI Infrastructure · Interactive Lab
Disaggregated NVMe fabrics, MLPerf v3.0 checkpoint telemetry, and sovereign cloud reference architectures.
Disaggregated NVMe fabrics, VAST DASE, Ceph, WEKA, and sovereign AI cloud data platforms.
Explore interactive architecture diagrams, calculate GPU idle-time financial stalls, compare erasure coding math, and inspect 1.25T parameter checkpoint benchmarks.
GPU Processing Pipelines · Deep Dive #18
Inside the GPU processing pipeline: backpropagation, distributed all-reduce, autoregressive decoding, and KV-cache architectures.
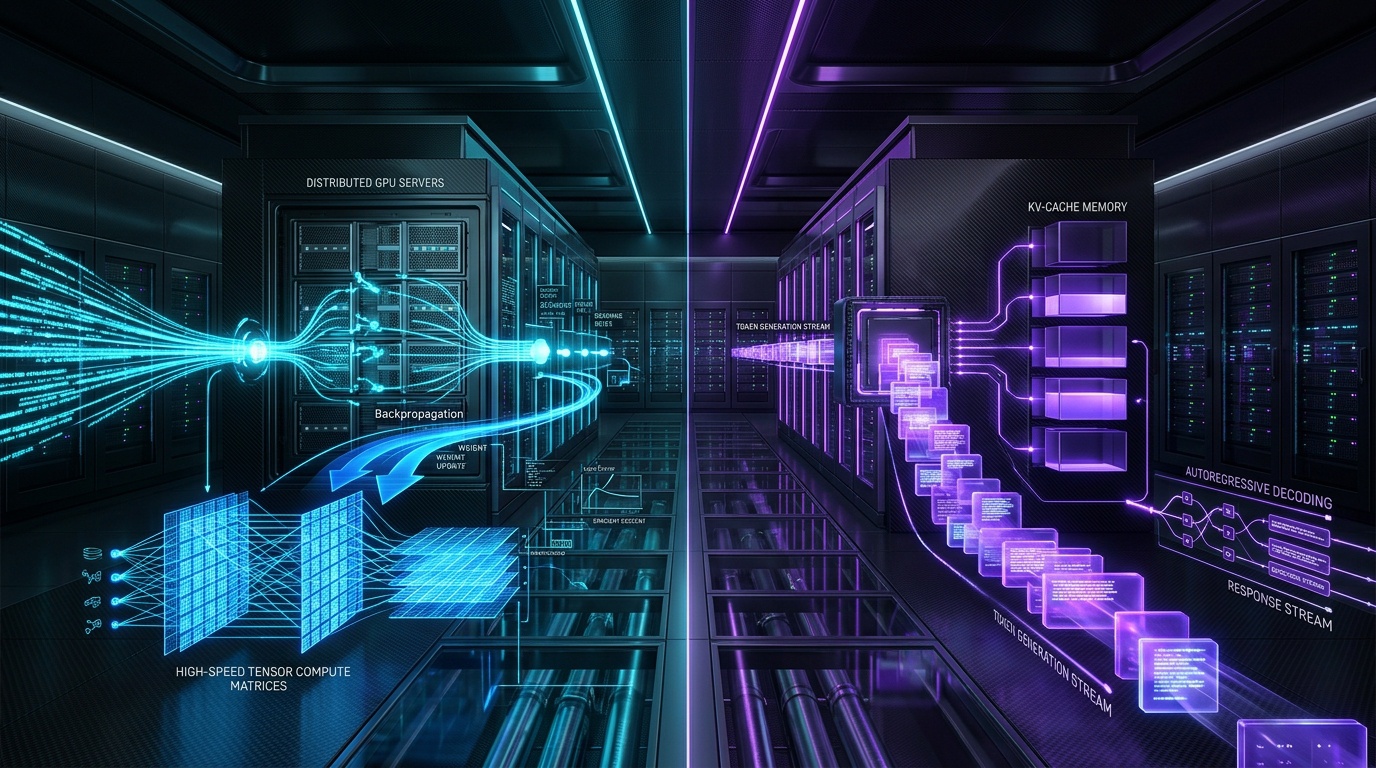
From backprop and all-reduce synchronization to token generation, KV caching, and memory offloading.
The architectural breakdown of GPU compute, memory consumption, storage dependencies, and networking topologies across AI model training and LLM inference. Includes interactive 7-stage vs 5-stage pipeline simulation.
GPU Computing · Inference Memory Architecture
GPU HBM3e, dynamic KV-cache scaling, GPUDirect Storage, and WEKA NeuralMesh distributed memory fabrics.
Why 70B models starve 8-way GPU nodes during 128K multi-agent inference—and how to fix it.
How modern inference engines turn GPU HBM, host DDR5, local NVMe, and distributed parallel storage into a unified memory tier. Includes interactive KV-cache capacity modeling and GPUDirect data paths.
Architectural Taxonomy · Topic Hubs
Structured knowledge hubs grouping our foundational pillars, protocol implementations, and benchmarks.
Engineering Build Log
In-depth technical blueprints, runtime harnesses, MCP protocols, and multi-agent systems architectures.
DEEP DIVE · #01 / THE LOCAL LAB
Windows, Python and Google ADK. A real local build, mistakes included.
DEEP DIVE · #02 / AGENT ARCHITECTURE
Four agent-building paths. The trade-offs behind choosing the right one.
DEEP DIVE · #03 / MCP & TOOLING
Wiring local MCP servers with Python and SQLite. Connect your tools. Keep control.
DEEP DIVE · #04 / TOOL ARCHITECTURE
Tool routing, least-privilege scoping, and evaluation. Avoid the tool-explosion trap.
DEEP DIVE · #06 / TOKENOMICS
Why Byte-Pair Encodings break multi-agent loops and how to fix subword fragmentation.
DEEP DIVE · #07 / MCP GATEWAYS
Streamable HTTP architecture, high-throughput agent gateways, and legacy SSE migration.
DEEP DIVE · #10 / SESSION SURGERY
How multi-turn transcripts explode token bills to 2.6M tokens, and surgical pruning fixes.
DEEP DIVE · #13 / STATE PERSISTENCE
Maintaining long-running agent coherence with structured state handover checkpoints.
DEEP DIVE · #15 / VOICE TELEPHONY
Bland AI, ElevenLabs, Retell, Vapi & 4 others benchmarked on latency, HIPAA security, and ROI.
DEEP DIVE · #16 / STORAGE ARCHITECTURE
NVMe fabrics, VAST DASE, Ceph, WEKA, DDN, and sovereign AI cloud data platforms in 2026.
DEEP DIVE · #17 / AI MEMORY HIERARCHY
GPU HBM, KV cache scaling, GPUDirect Storage, and WEKA NeuralMesh distributed memory fabrics.
DEEP DIVE · #18 / GPU PROCESSING PIPELINES
NEWFrom backprop and all-reduce to token generation, KV caching, and memory offloading.
From foundation models to runtime harnesses, agent loops, and enterprise ontologies.
Watch the narrated video intro on the left for the rapid bird's-eye view, or dive directly into the complete production engineering blueprint.